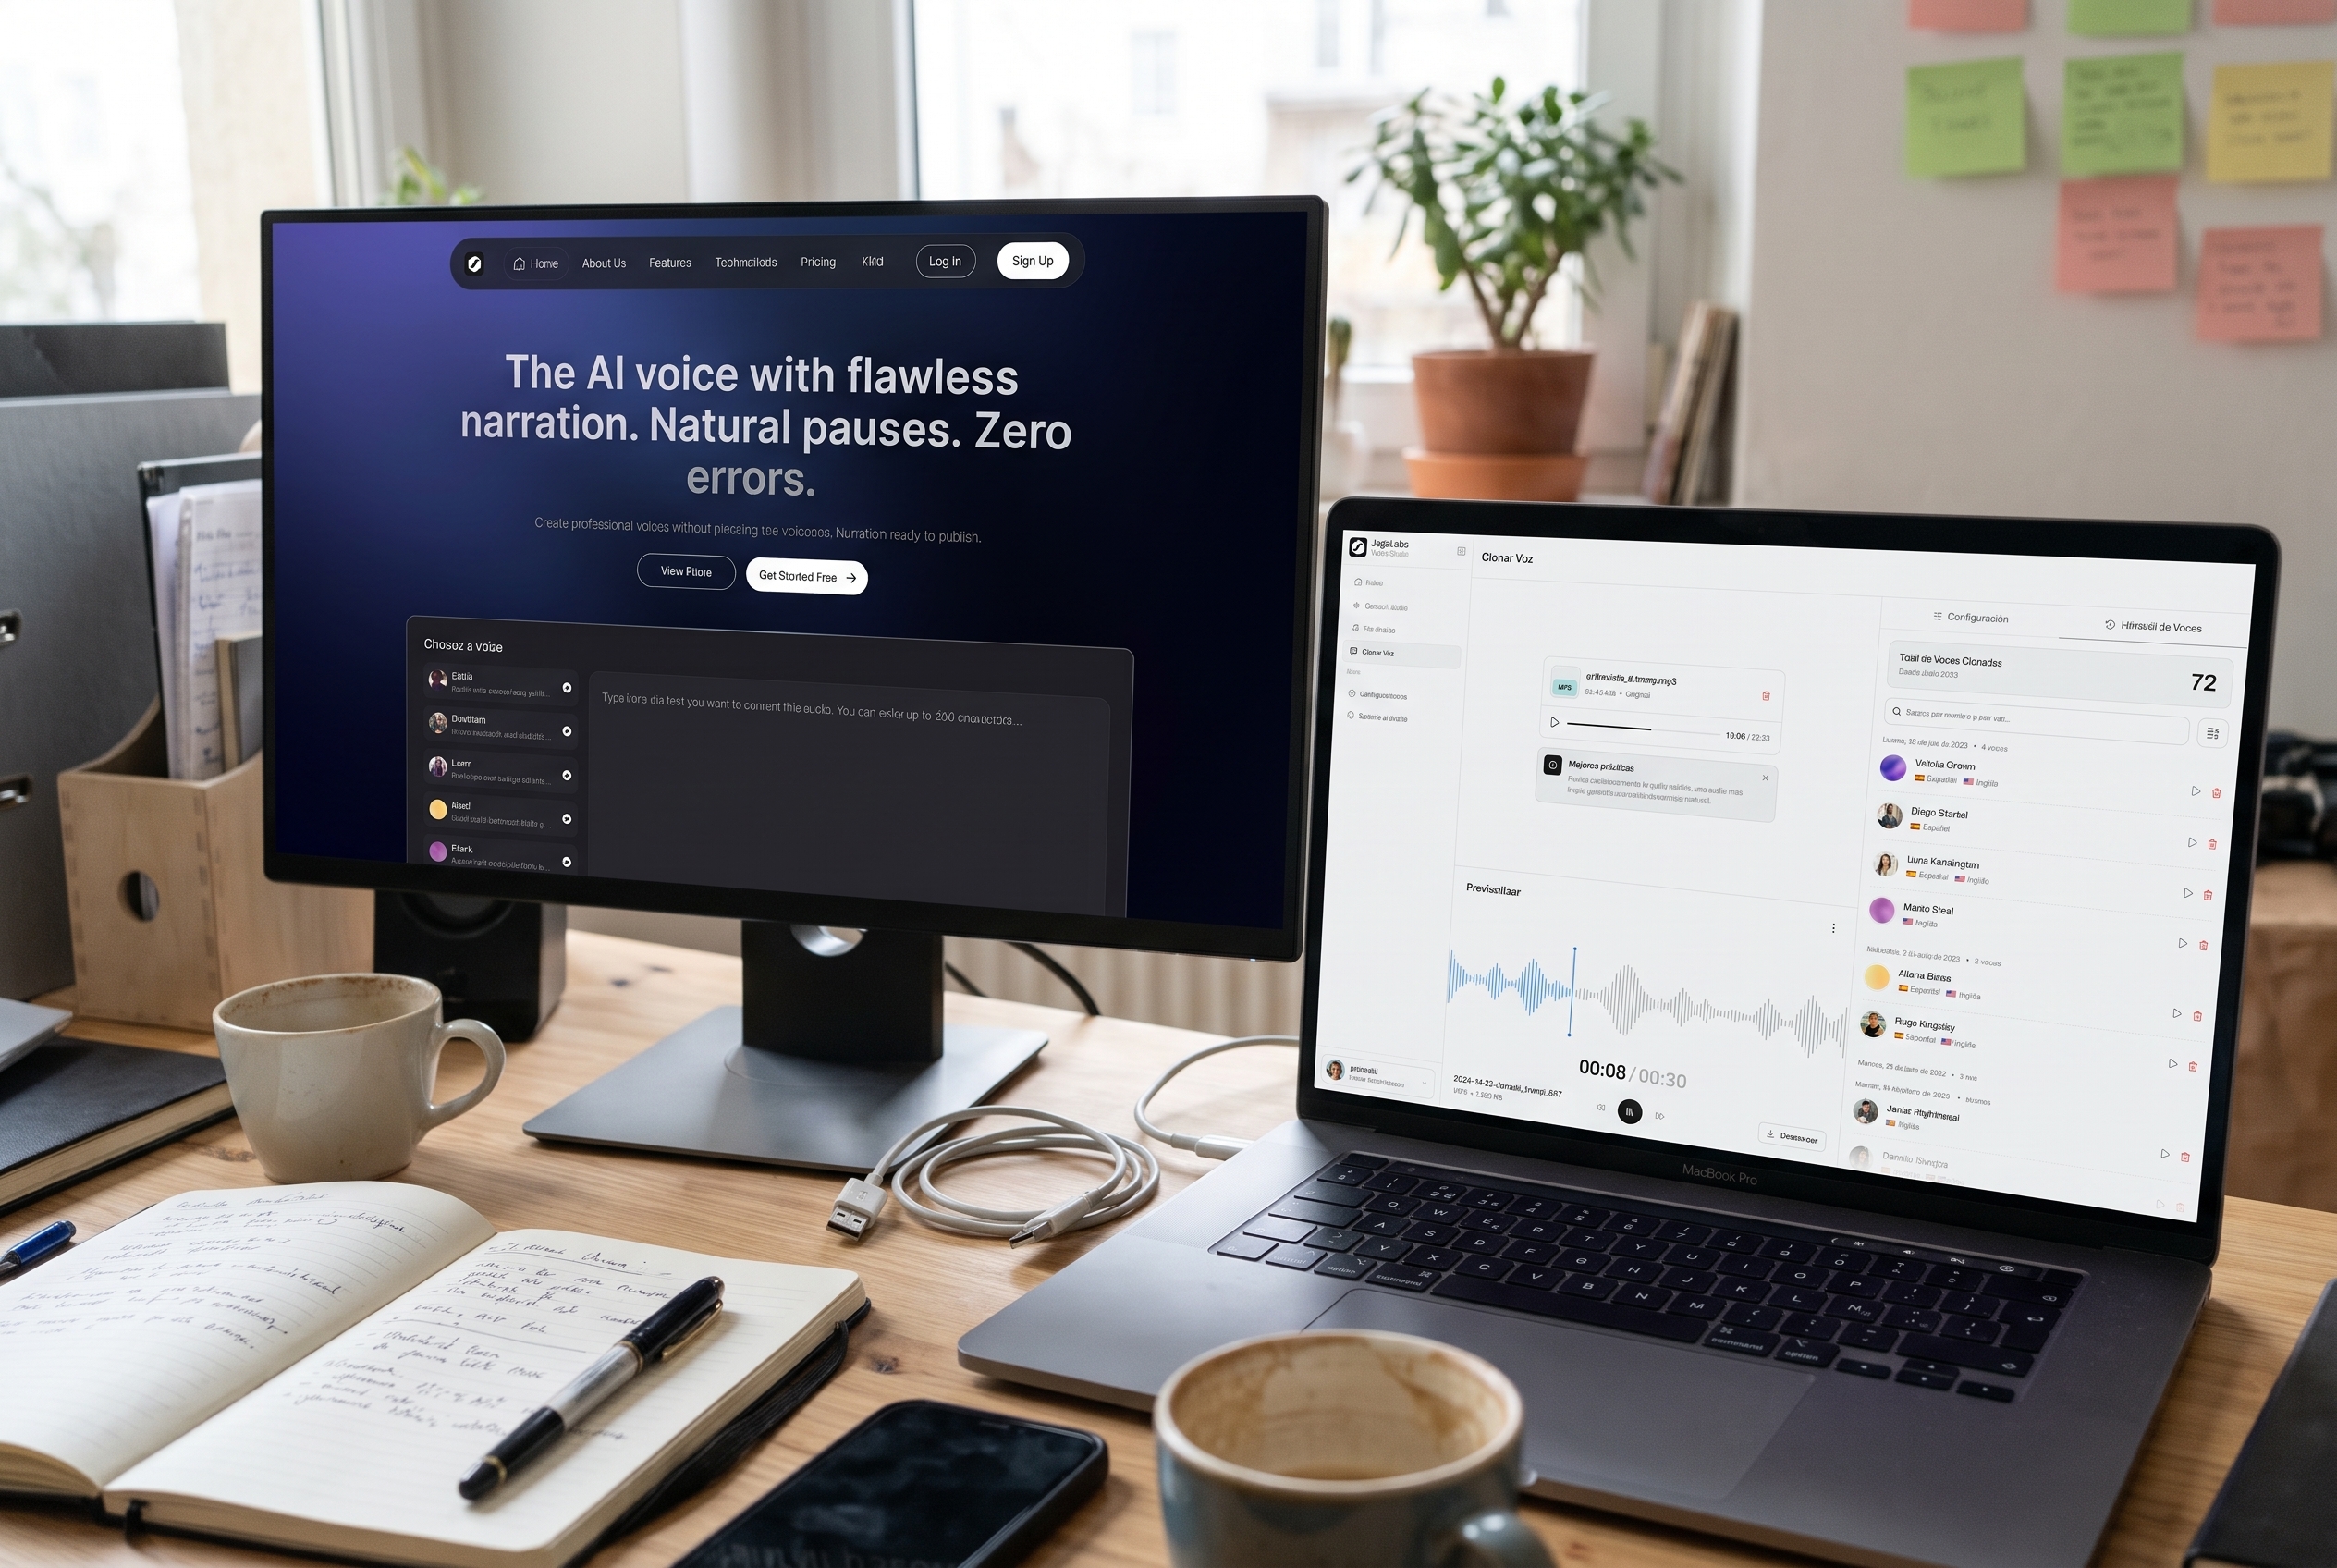
Results
Challenge
Most generative AI voice tools in 2024 fell into two buckets: clunky academic Python notebooks or toy chat windows with sparkles icons. If you run a faceless documentary channel or produce daily video essays, generating voiceovers was death by a thousand cuts. You pasted a script, hit generate, got a 3-minute MP3 chunk, and discovered the voice stumbled over a comma on paragraph four. Your only option was burning more credits to re-roll the whole block, hoping the model would randomly pronounce it right this time, then manually stitching 15 separate files together on a Premiere timeline.
Creators were losing 15+ hours a week fighting these tools. The core UX broke down across three pain points: black-box credit meters where failed takes burned real money, arbitrary generation caps that forced endless audio splicing, and zero inline control over pacing, breath pauses, or phonetic inflection.
Our key design question:
How do we build an editor-first studio that lets creators generate up to 60 minutes of broadcast-ready audio in one pass, with sub-400ms streaming feedback and instant 30-second voice cloning?
We had to scrap the chat-box paradigm entirely. Creative workflows demand direct canvas manipulation, timeline scrubbing, and predictable feedback loops: not waiting 45 seconds for a black-box cloud server to render an opaque audio blob.
Research
To see where creators actually hit walls, we shadowed 18 video editors and narrative creators through their real weekly production sprints and ran teardowns on four market-leading speech platforms.
Audited ElevenLabs, Fish Audio, InVideo, and HeyGen. Followed 18 creators across YouTube video essay channels, audiobook publishing, and commercial voiceover studios, tracking every time they alt-tabbed out of their browser to fix audio in Audacity or Premiere.
Workshop
Ran remote cross-time-zone sprints with our Founder (Dubai), Lead Backend Architect (Colombia), and Frontend Engineer (Argentina) to lock down studio UX specs, streaming audio thresholds, and WebGL waveform performance budgets.
Over three focused sessions, we aligned our speech generation APIs with creator mental models. We killed complex DAW menus, opted for an editor-first canvas with inline pacing tags, and agreed on a 60 FPS Web Audio API rendering budget on mid-tier laptops.
Workshop Execution Framework
1. Creator Workflow Mapping
Mapped the creator path from raw script pasting to final MP3/WAV stem export. We eliminated nested configuration dialogs and modal wizards, reframing the core product into a single-viewport studio with inline audio scrubbing and direct phoneme controls.
Replaced fragmented sub-pages with a unified desktop layout combining a 20,000-character script editor, voice selector sidebar, and an interactive waveform scrubber on a single screen.
2. Waveform Visualizer Prototyping
Prototyped audio visualization options. Static bar graphs felt dead, but full 3D shaders dragged CPU performance down. We built a customized Three.js WebGL particle field that ripples dynamically with audio playback while staying pinned at 60 FPS.
Benchmarked 5 interactive particle shaders with the frontend engineer, locking down a lightweight vertex shader that runs smoothly on standard integrated laptop GPUs without battery drain.
3. Pricing Card Architecture
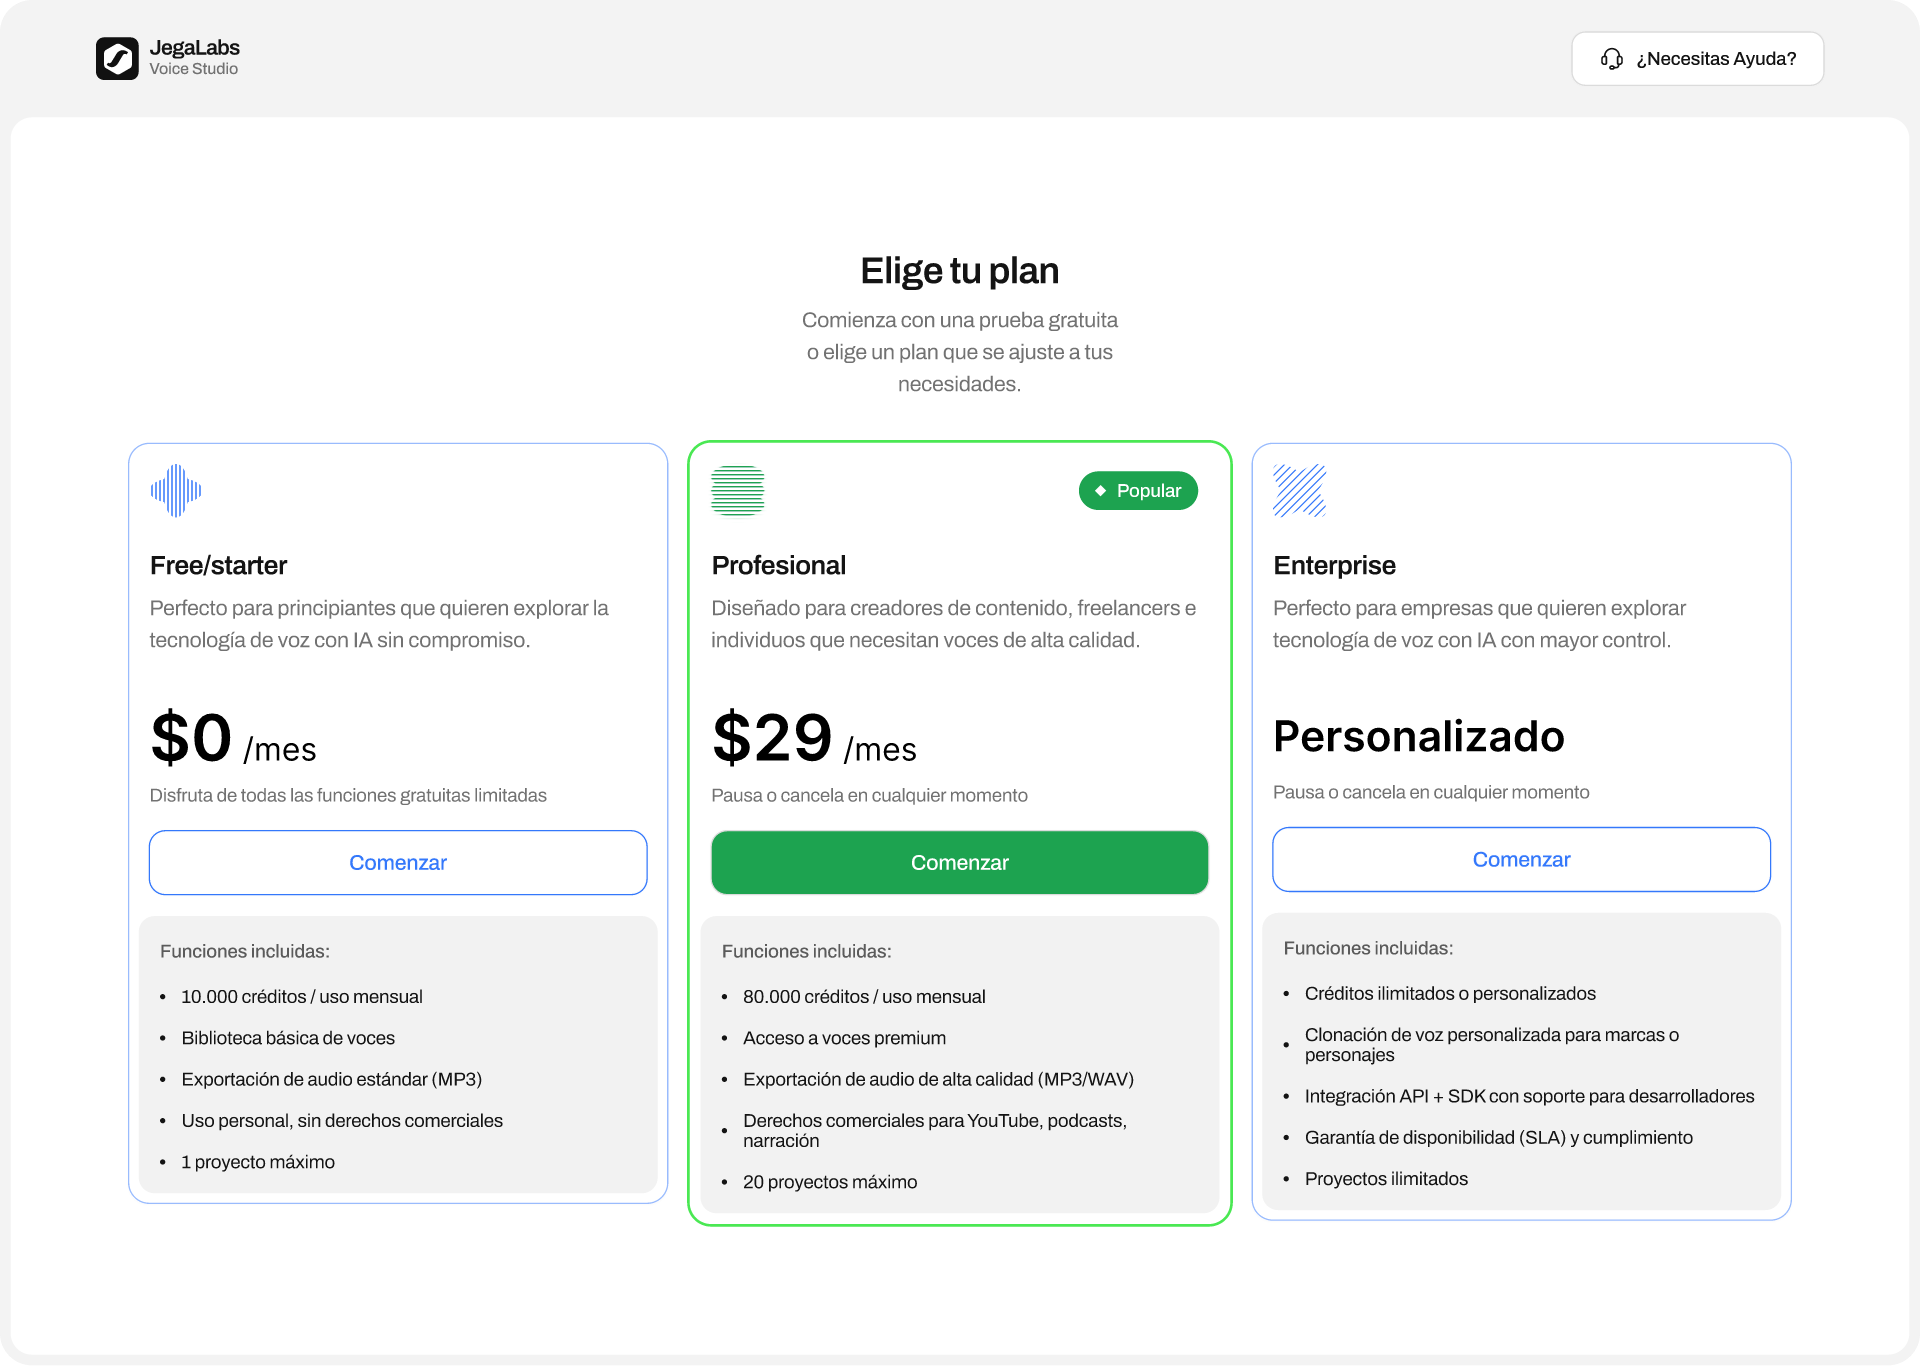
Reworked pricing tier hierarchy with the founder. Scrapped dark, low-contrast cards in favor of clean white surfaces with a highlighted emerald Pro tier ($29/mo), transparent credit quotas, and clear YouTube licensing badges.
Standardized a 3-tier structure (Free $0 / Pro $29 / Enterprise Custom) with explicit character limits, eliminating hesitation at checkout.
Technical Specification & Design Token Architecture
Delivered a complete 15-screen production design system, responsive Figma components, and full developer handoff documentation. The architecture defined strict token contracts for color scales, typography hierarchies, and stateful audio player controls.
Provided typed API contracts, component states, and CSS custom properties that enabled rapid frontend implementation with zero visual drift.
Design
Text-to-Speech Studio & Waveform Scrubber
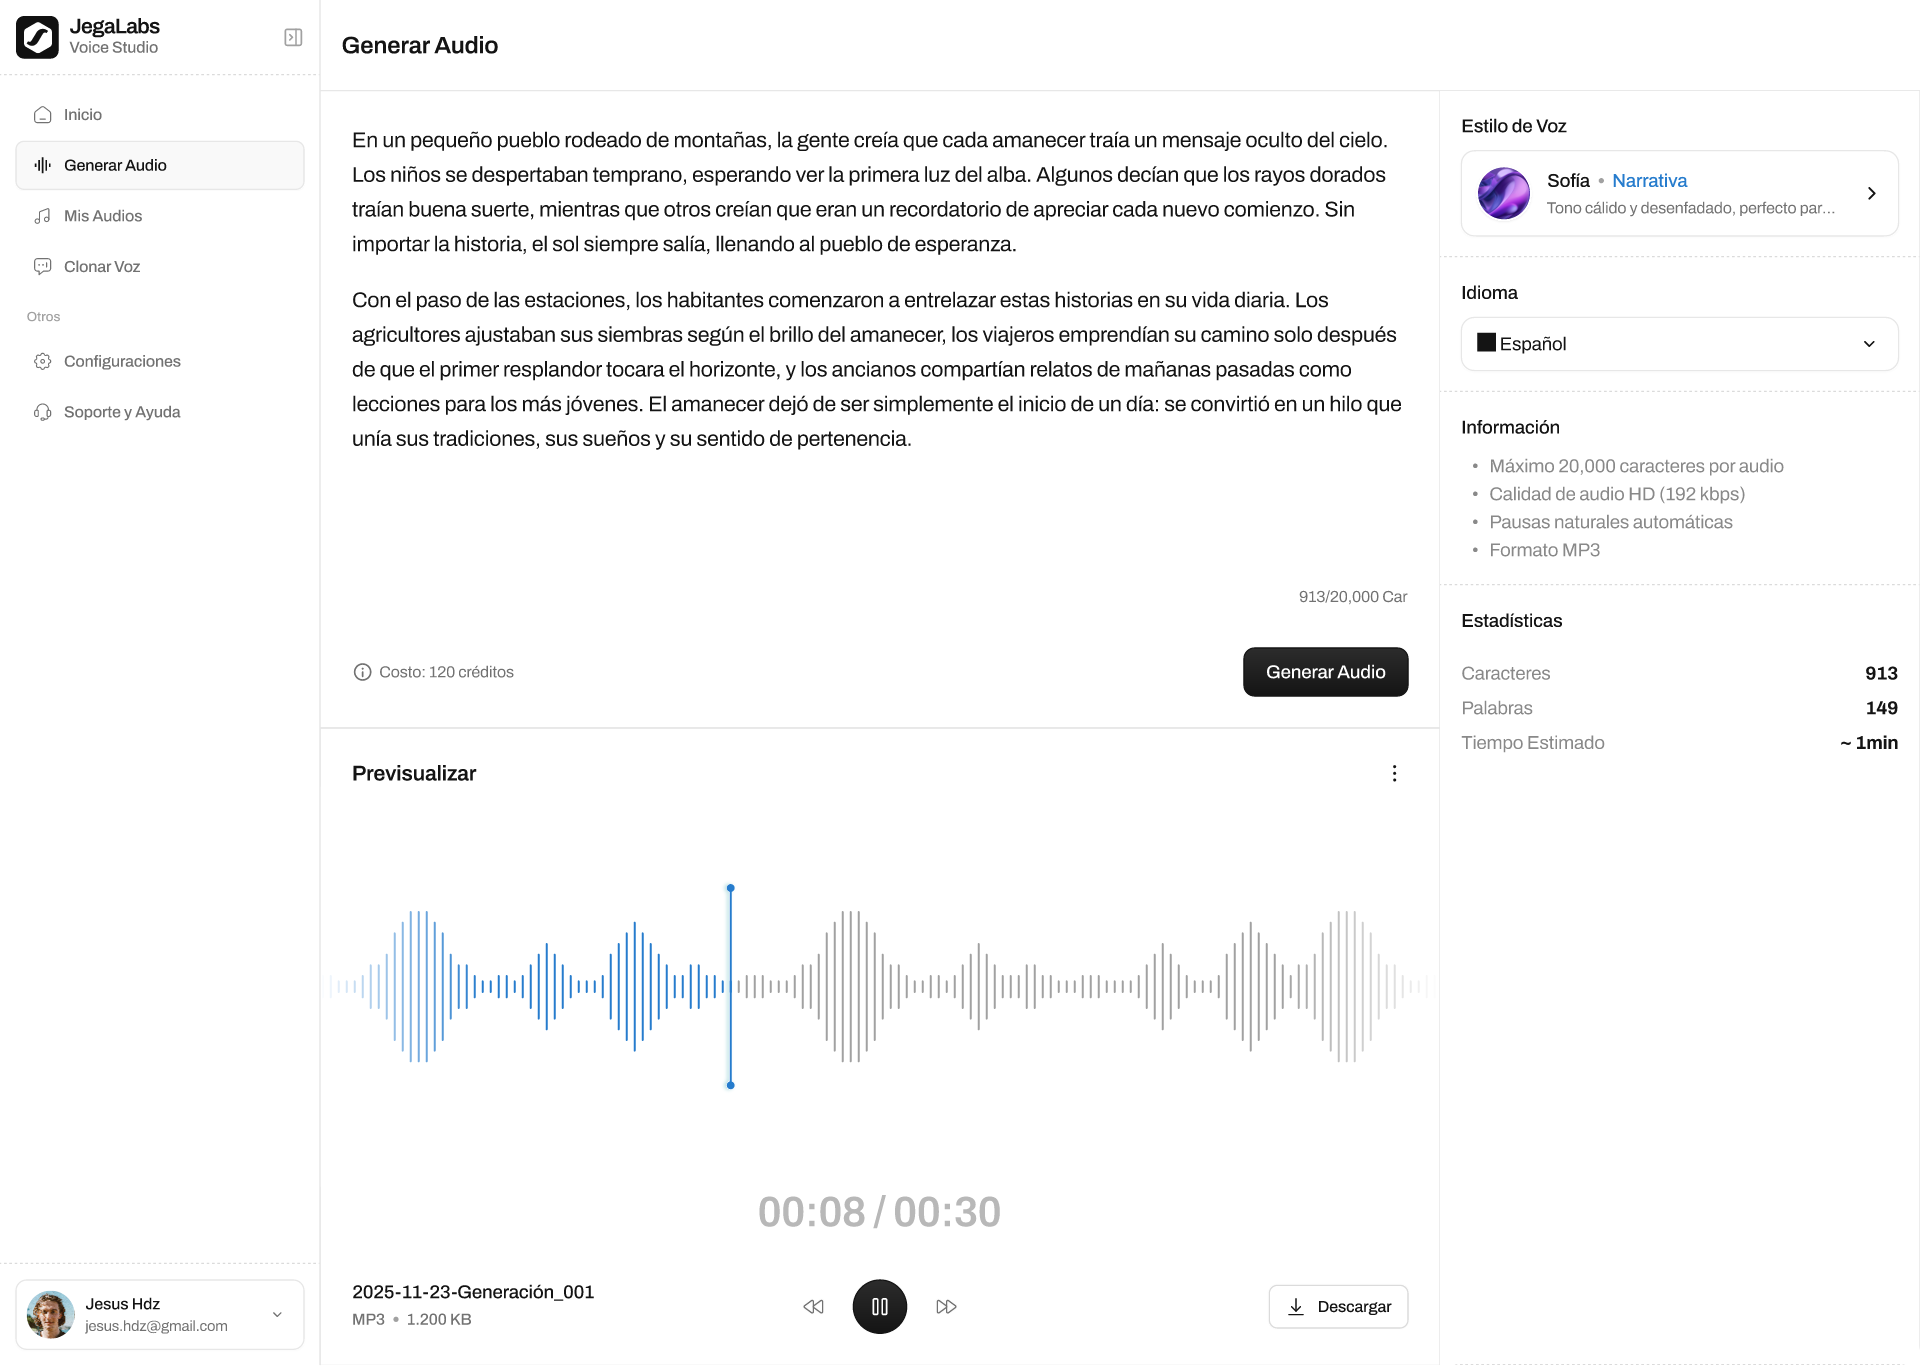
The studio workspace is built around uninterrupted creative flow. Rather than burying controls behind modal popups, the entire generation loop lives on a single, distraction-free canvas. Creators write or paste long-form scripts into an expansive 20,000-character editor with live character counting, narration time estimates, and credit costs.
Directly below the text area, an interactive waveform scrubber renders playback at 60 FPS using the Web Audio API. Creators can scrub through generated audio, test specific syllables, and insert inline pacing tags like [pause: 300ms] or inflection tweaks before exporting broadcast-ready 192kbps MP3 or WAV stems with one click.
The right-hand inspector panel provides instant access to voice models (such as Studio Narrative Model • Warm Neutral), language selectors, and real-time generation stats without leaving the editor.
Instant Voice Cloning & Quality Gatekeeper
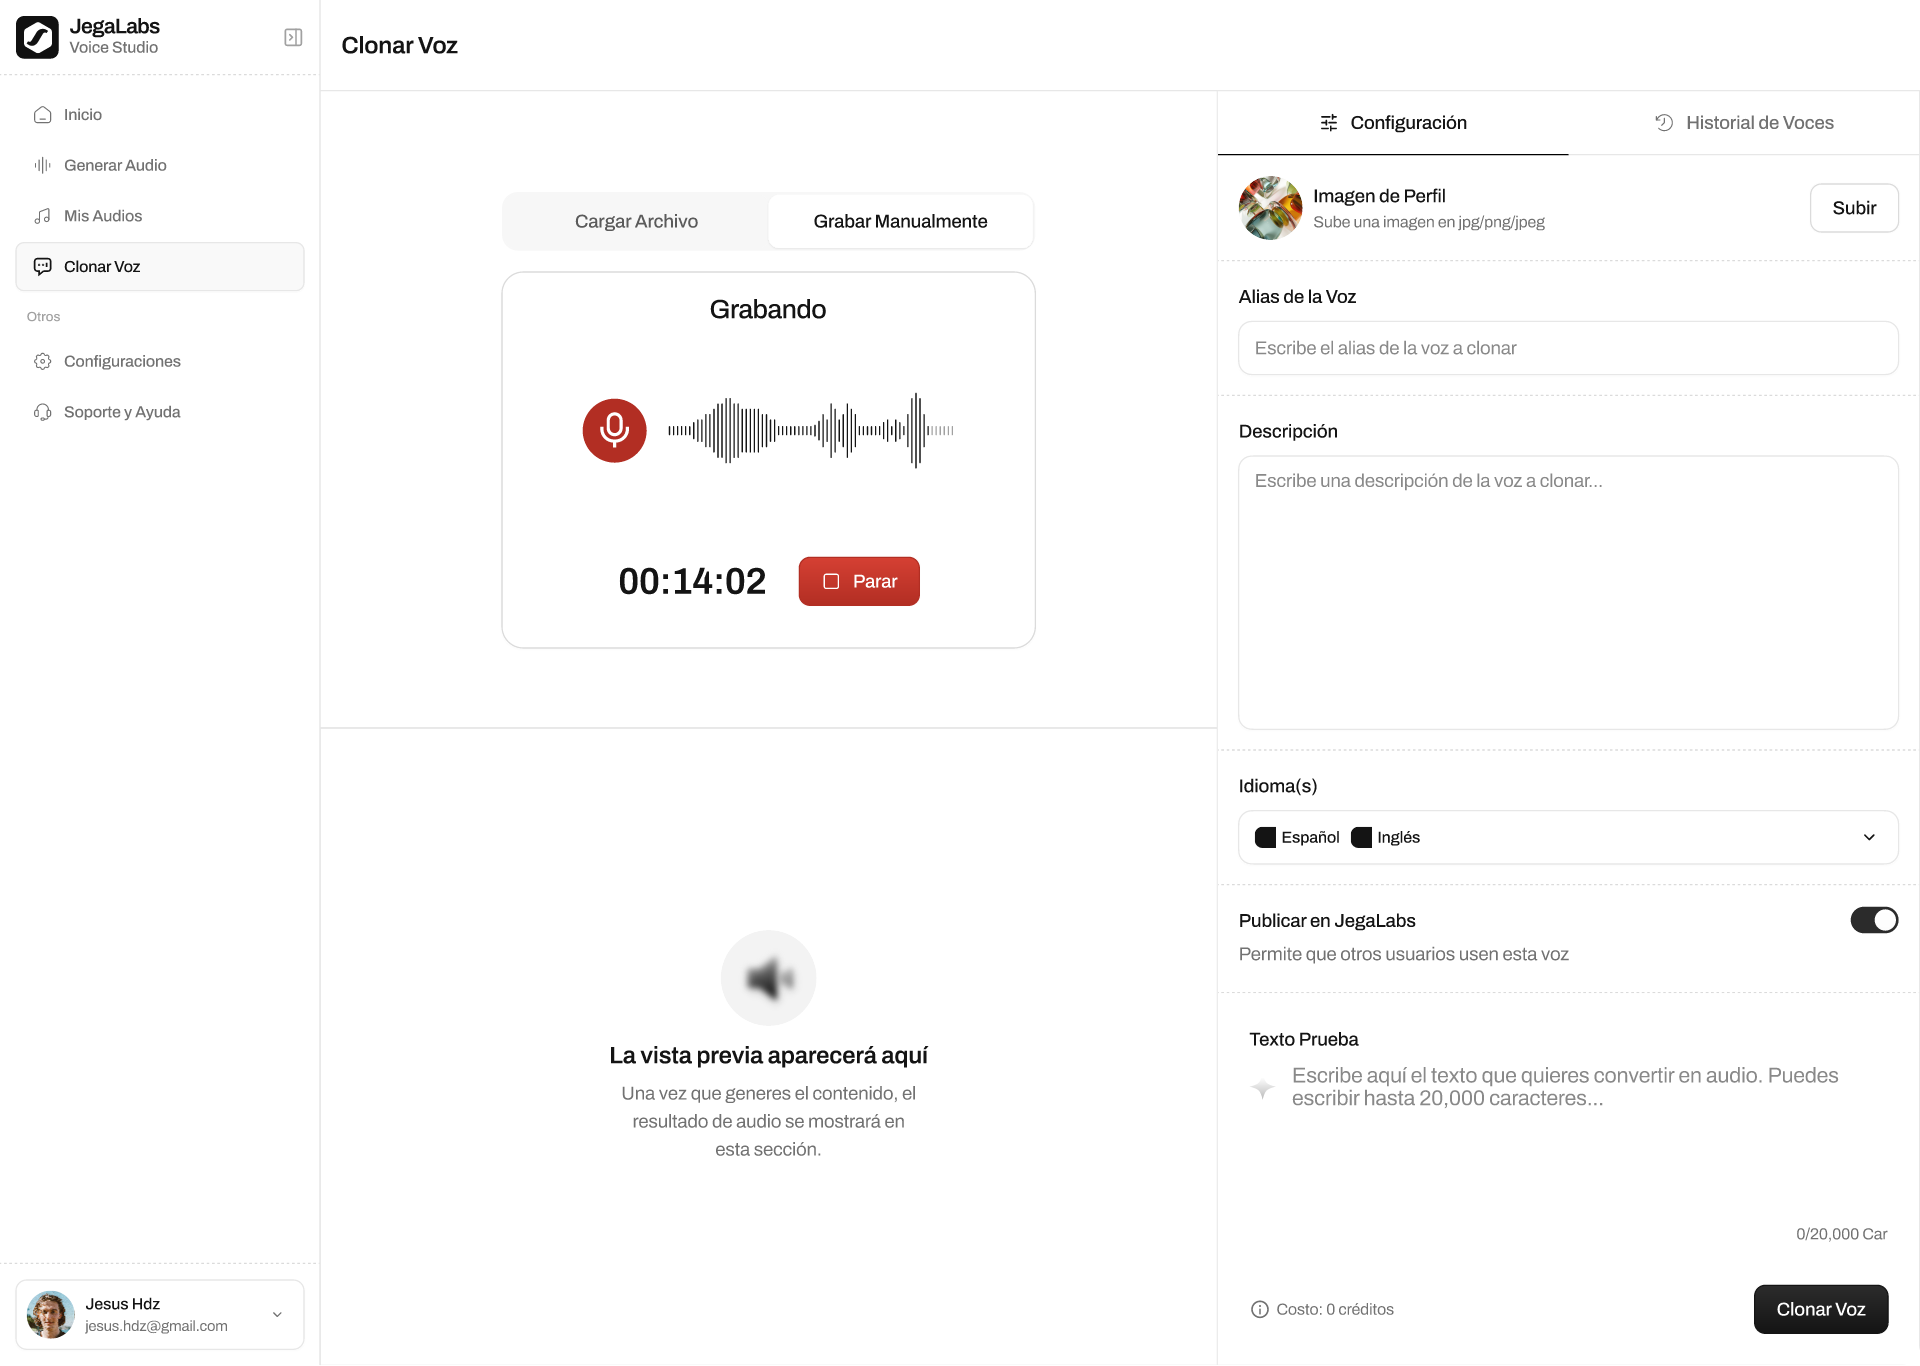
Voice cloning usually meant uploading gigabytes of training data and waiting 48 hours for an email notification. We compressed that into an intuitive two-step studio flow: Drag & Drop an existing audio track (MP3/WAV up to 50MB) or record directly in the browser via microphone.
During recording, a live decibel meter and timer validate signal clarity. The system runs an automated noise-floor analysis, checks for clipping, attaches metadata (voice alias, language, custom avatar), and publishes a usable custom voice model to the creator's library in under 2.5 minutes.
An inline best practices banner guides creators on room acoustics and microphone technique in plain language, preventing noisy training runs without technical audio jargon.
Community Voice Marketplace & Voice History
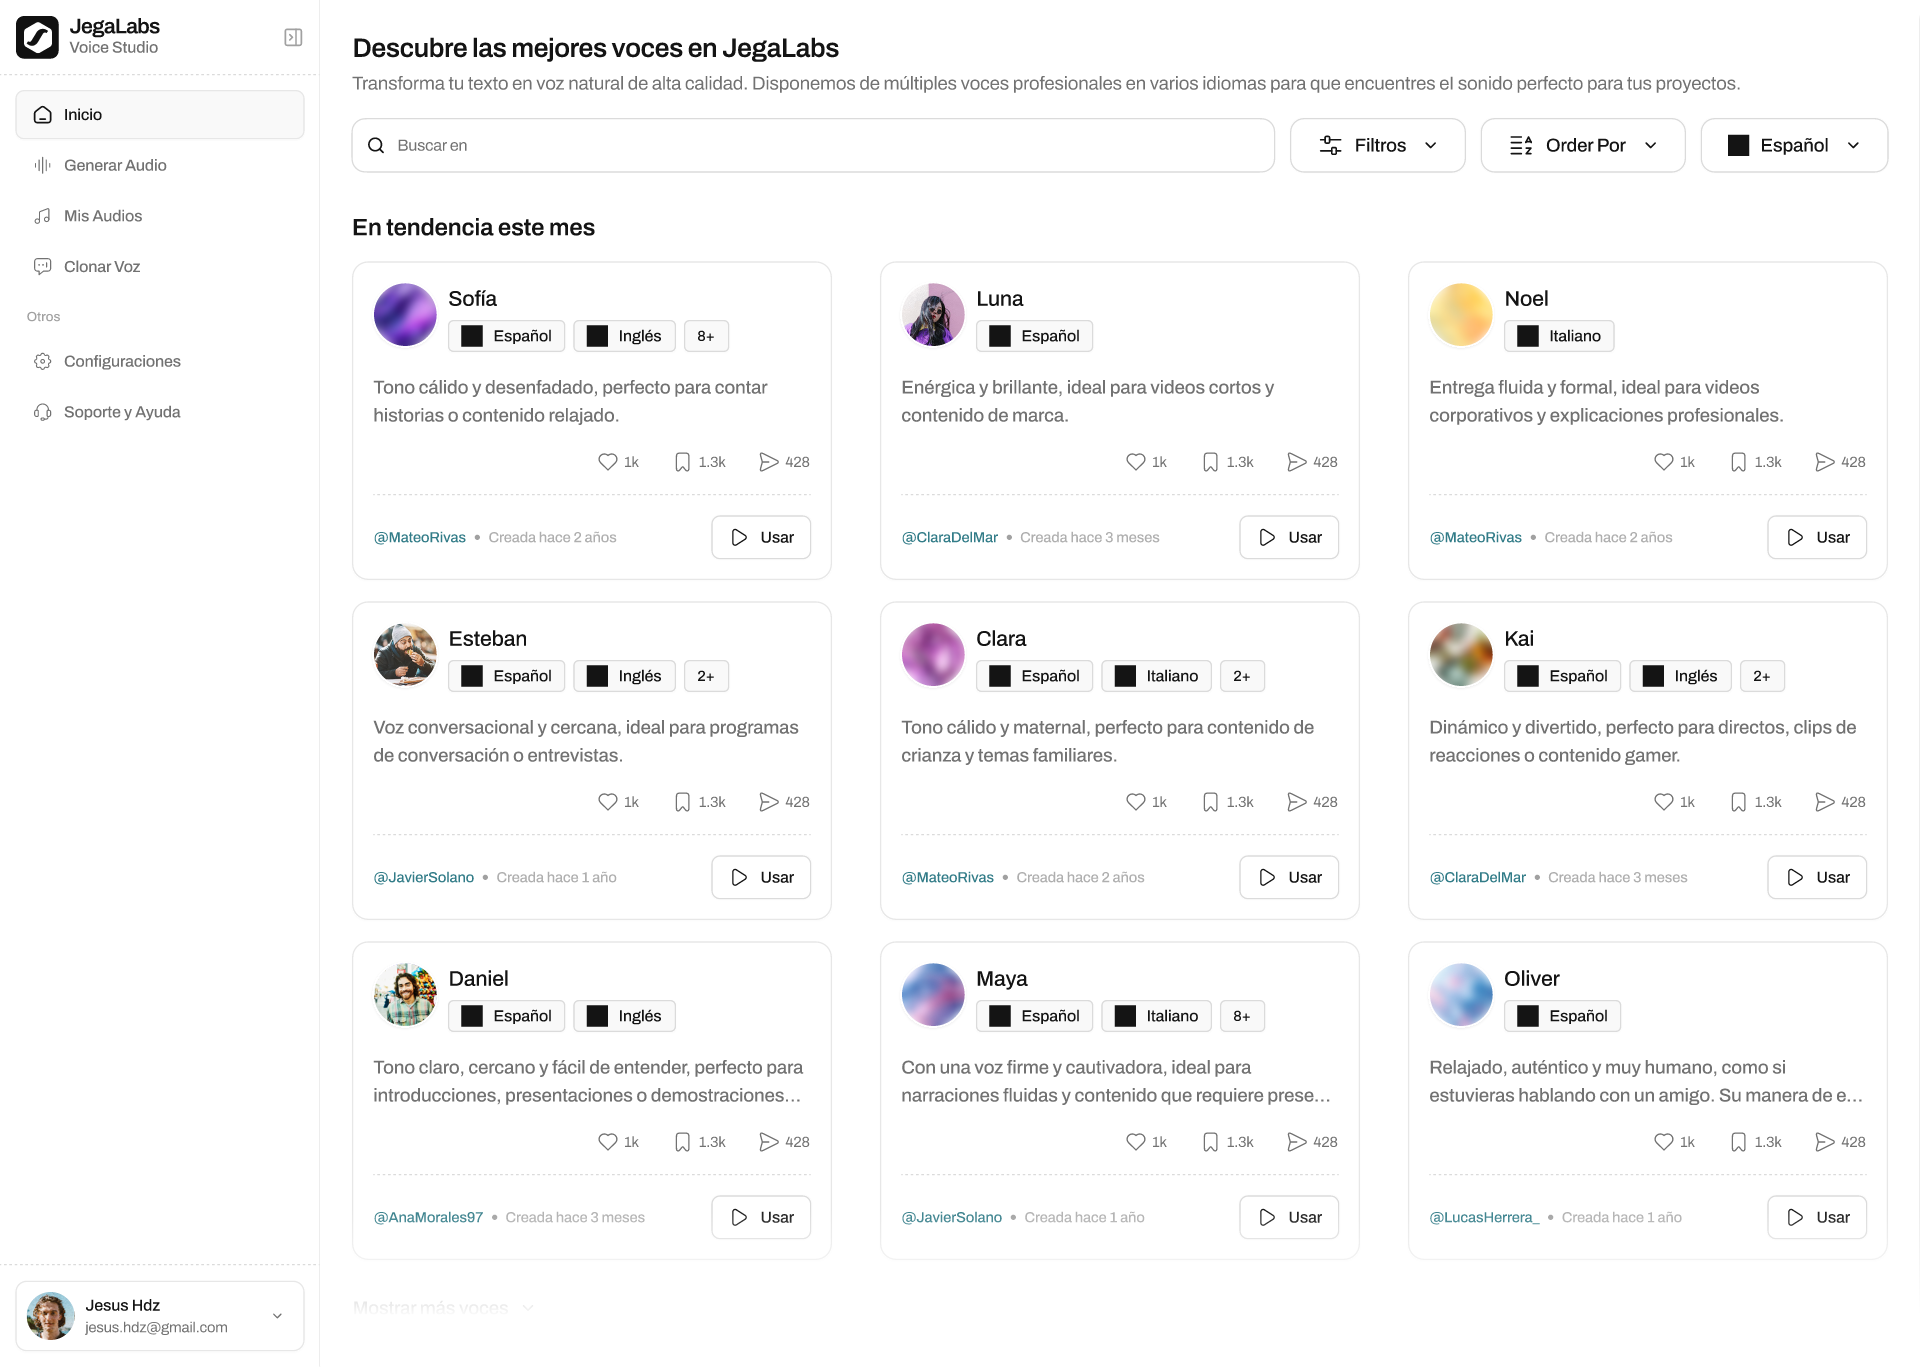
To make voice discovery effortless, we designed the Explore Voice Marketplace. Creators can browse dozens of verified voices filtered by acoustic tone and genre: Long-form Narrative, Social Media Promo, Corporate Briefing, Natural Dialogue, and Gaming Characters.
Each voice card features language tags, creator studio attribution (@creator_partner), community metrics, and an instant 5-second preview player. Clicking 'Use Voice' loads the profile directly into the editor without a page reload or state loss.
Creators manage their generated audio assets and saved clones in the 'Mis Audios' archive, with full-text search, language filtering, and batch stem export.
Transparent Subscription Architecture & Affiliate Portal
Working closely with the founder, we overhauled the pricing experience. We ditched dark, low-contrast cards for clean white surfaces featuring a prominent emerald Pro tier ($29/mo) and transparent quotas (80,000 monthly credits with commercial YouTube licensing rights).
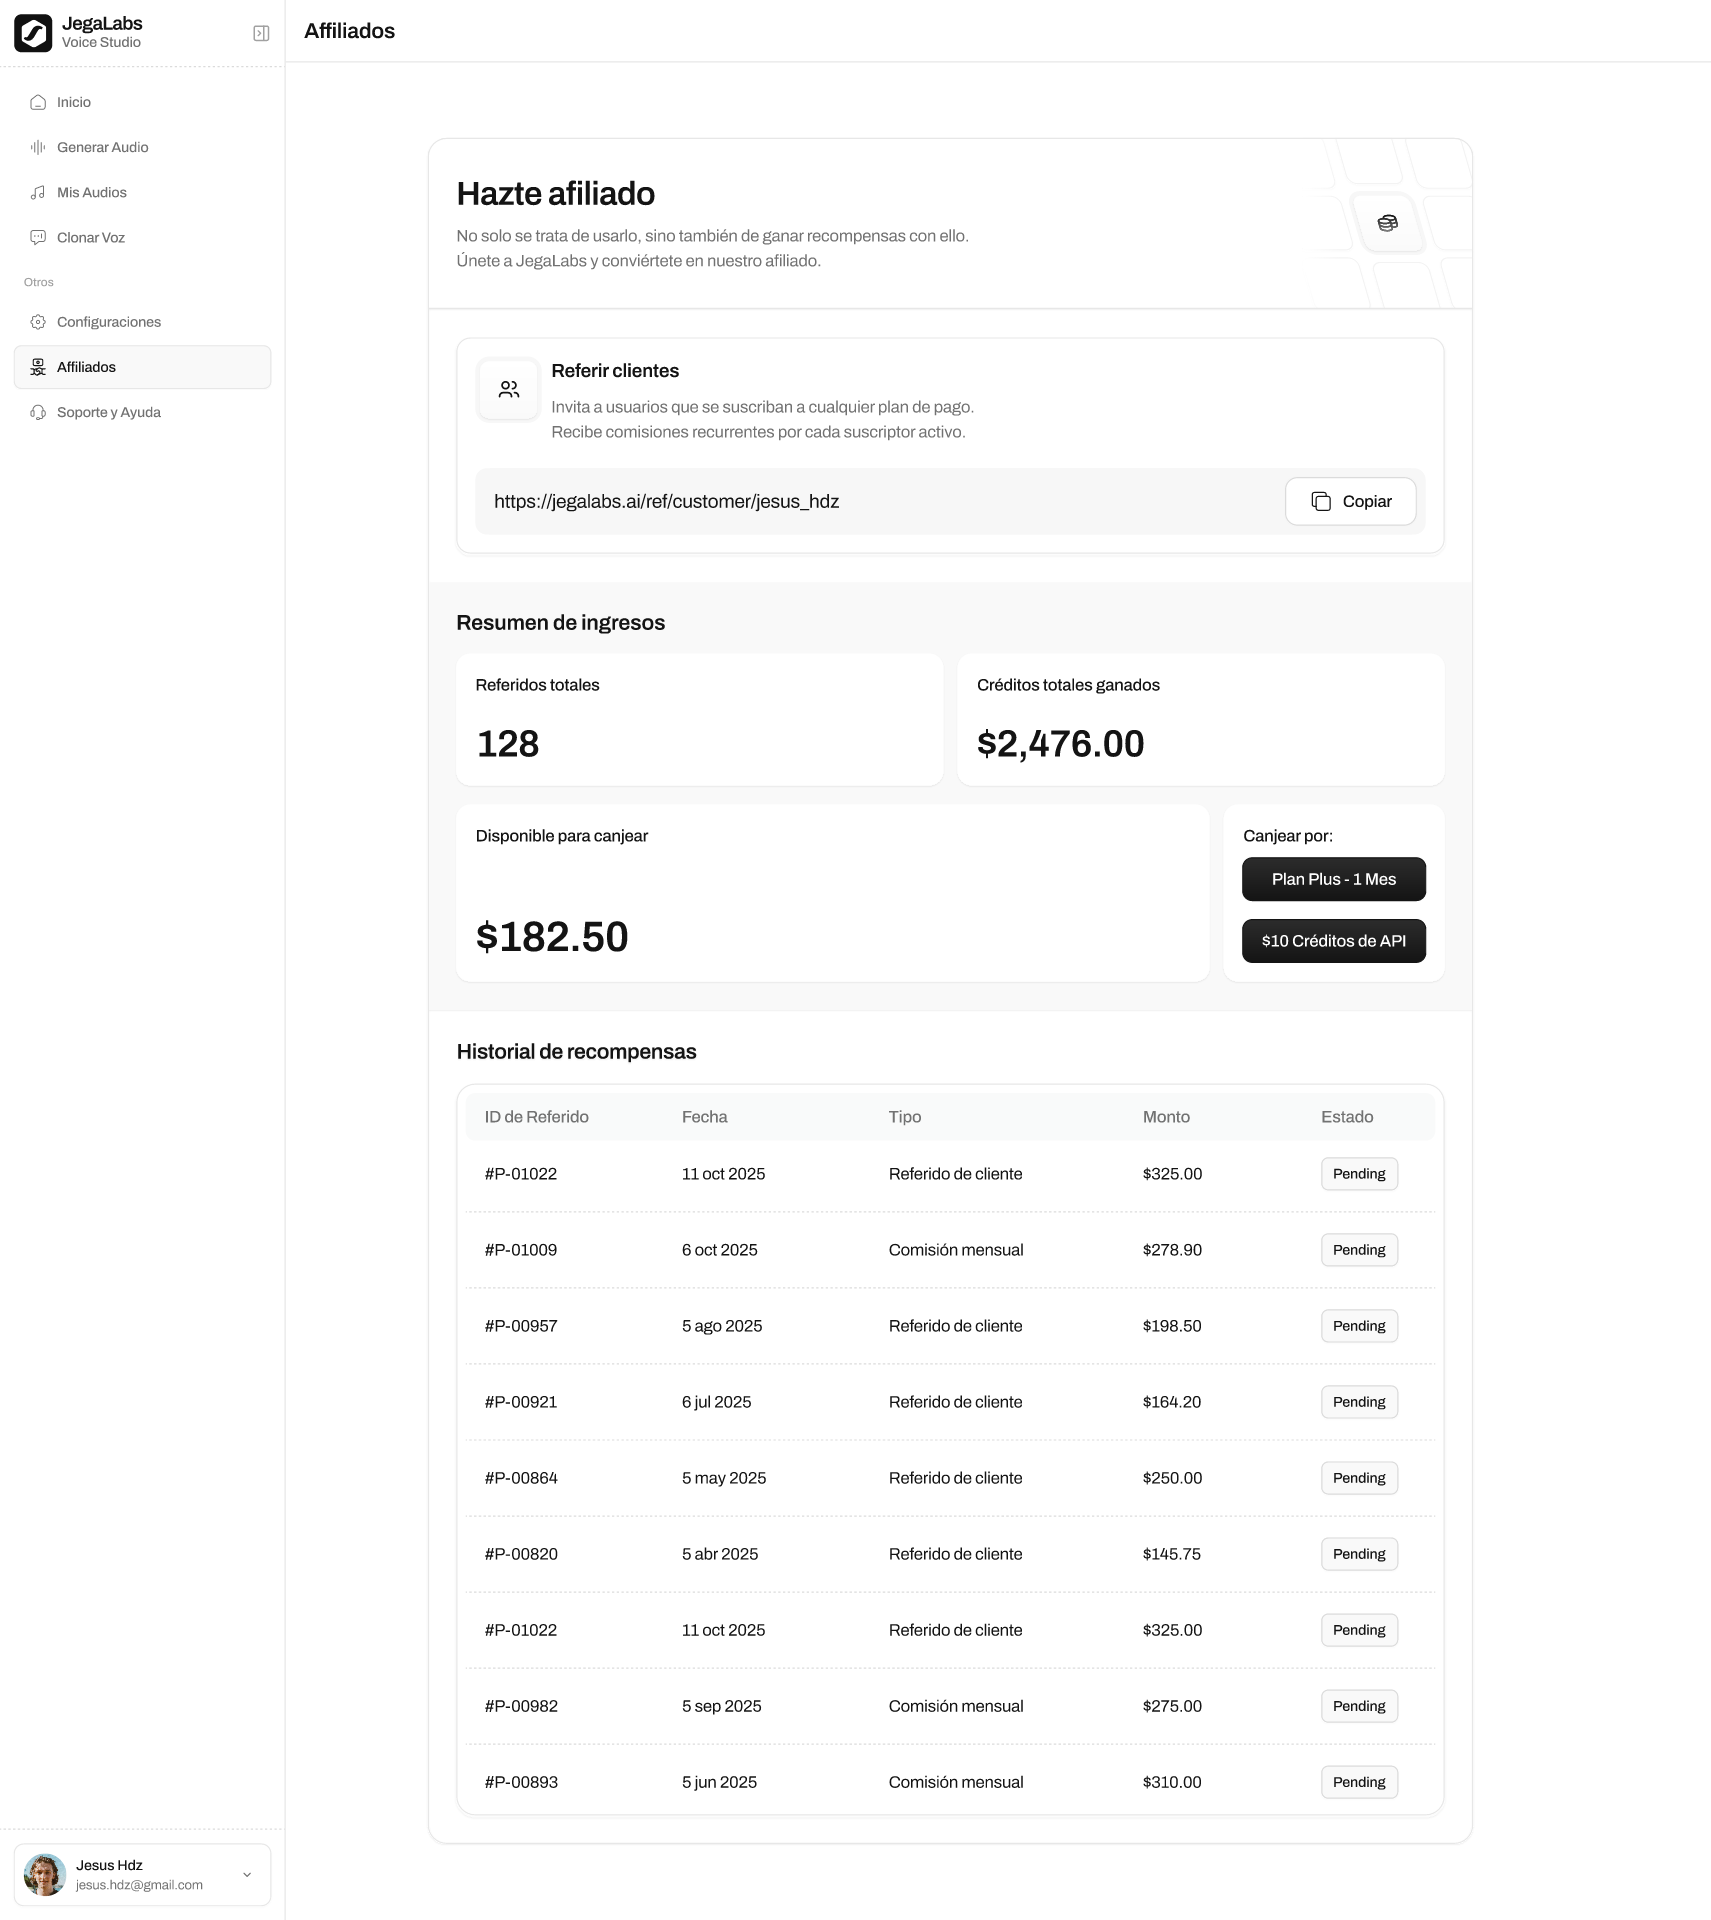
To power organic word-of-mouth growth, we designed a native Affiliate Portal. Creators generate custom referral links, track active referrals (128 total), monitor earned commissions ($2,476 earned), and cash out or redeem credits directly within their billing tab.
The payout ledger provides real-time status tracking (Pending, Paid) and automated alerts when credit balances reach threshold limits.
User Testing
To test whether our single-viewport studio and continuous generation pipeline solved creator friction, we ran moderated usability walkthroughs and comparative production trials across 22 independent video creators and audio editors.
Over a 3-week prototype testing sprint, we benchmarked real production workflows across YouTube video essays, podcast narrations, and agency commercial spots.
Testing Methodology & Participant Cohort
Moderated Studio Walkthroughs
Conducted 45-minute remote think-aloud sessions evaluating script editing, voice switching, waveform scrubbing, and stem export.
100% of participants generated long-form audio without asking for help, scoring task ease 4.8 out of 5 on the single-screen layout.
Comparative Production Benchmarking
Compared end-to-end turnaround between legacy chunk-based generation (ElevenLabs) and our 60-minute continuous streaming pipeline.
Total production time for a 20-minute video narration plunged from 3 hours 45 minutes to just 35 minutes, eliminating external audio slicing.
Key Usability Findings
91% Voice Likeness Rating
Creators highlighted punctuation-aware breathing pauses, noting the output sounded natural enough for commercial publishing without manual EQ or audio touchups.
Blinded audio tests with 80 podcast listeners showed 88% could not distinguish our continuous narration from professional studio voice actor recordings.
64% Lower Pricing Hesitation
Displaying character counts and estimated narration minutes upfront killed anxiety around burning credits, directly lifting Pro tier checkout conversion.
Creators highlighted the visible 80,000 credit pool and clear YouTube commercial rights as the decisive factor in upgrading to the $29/mo plan.
Iteration
1. Evolving from flat frequency bars to organic 3D particle wavefields
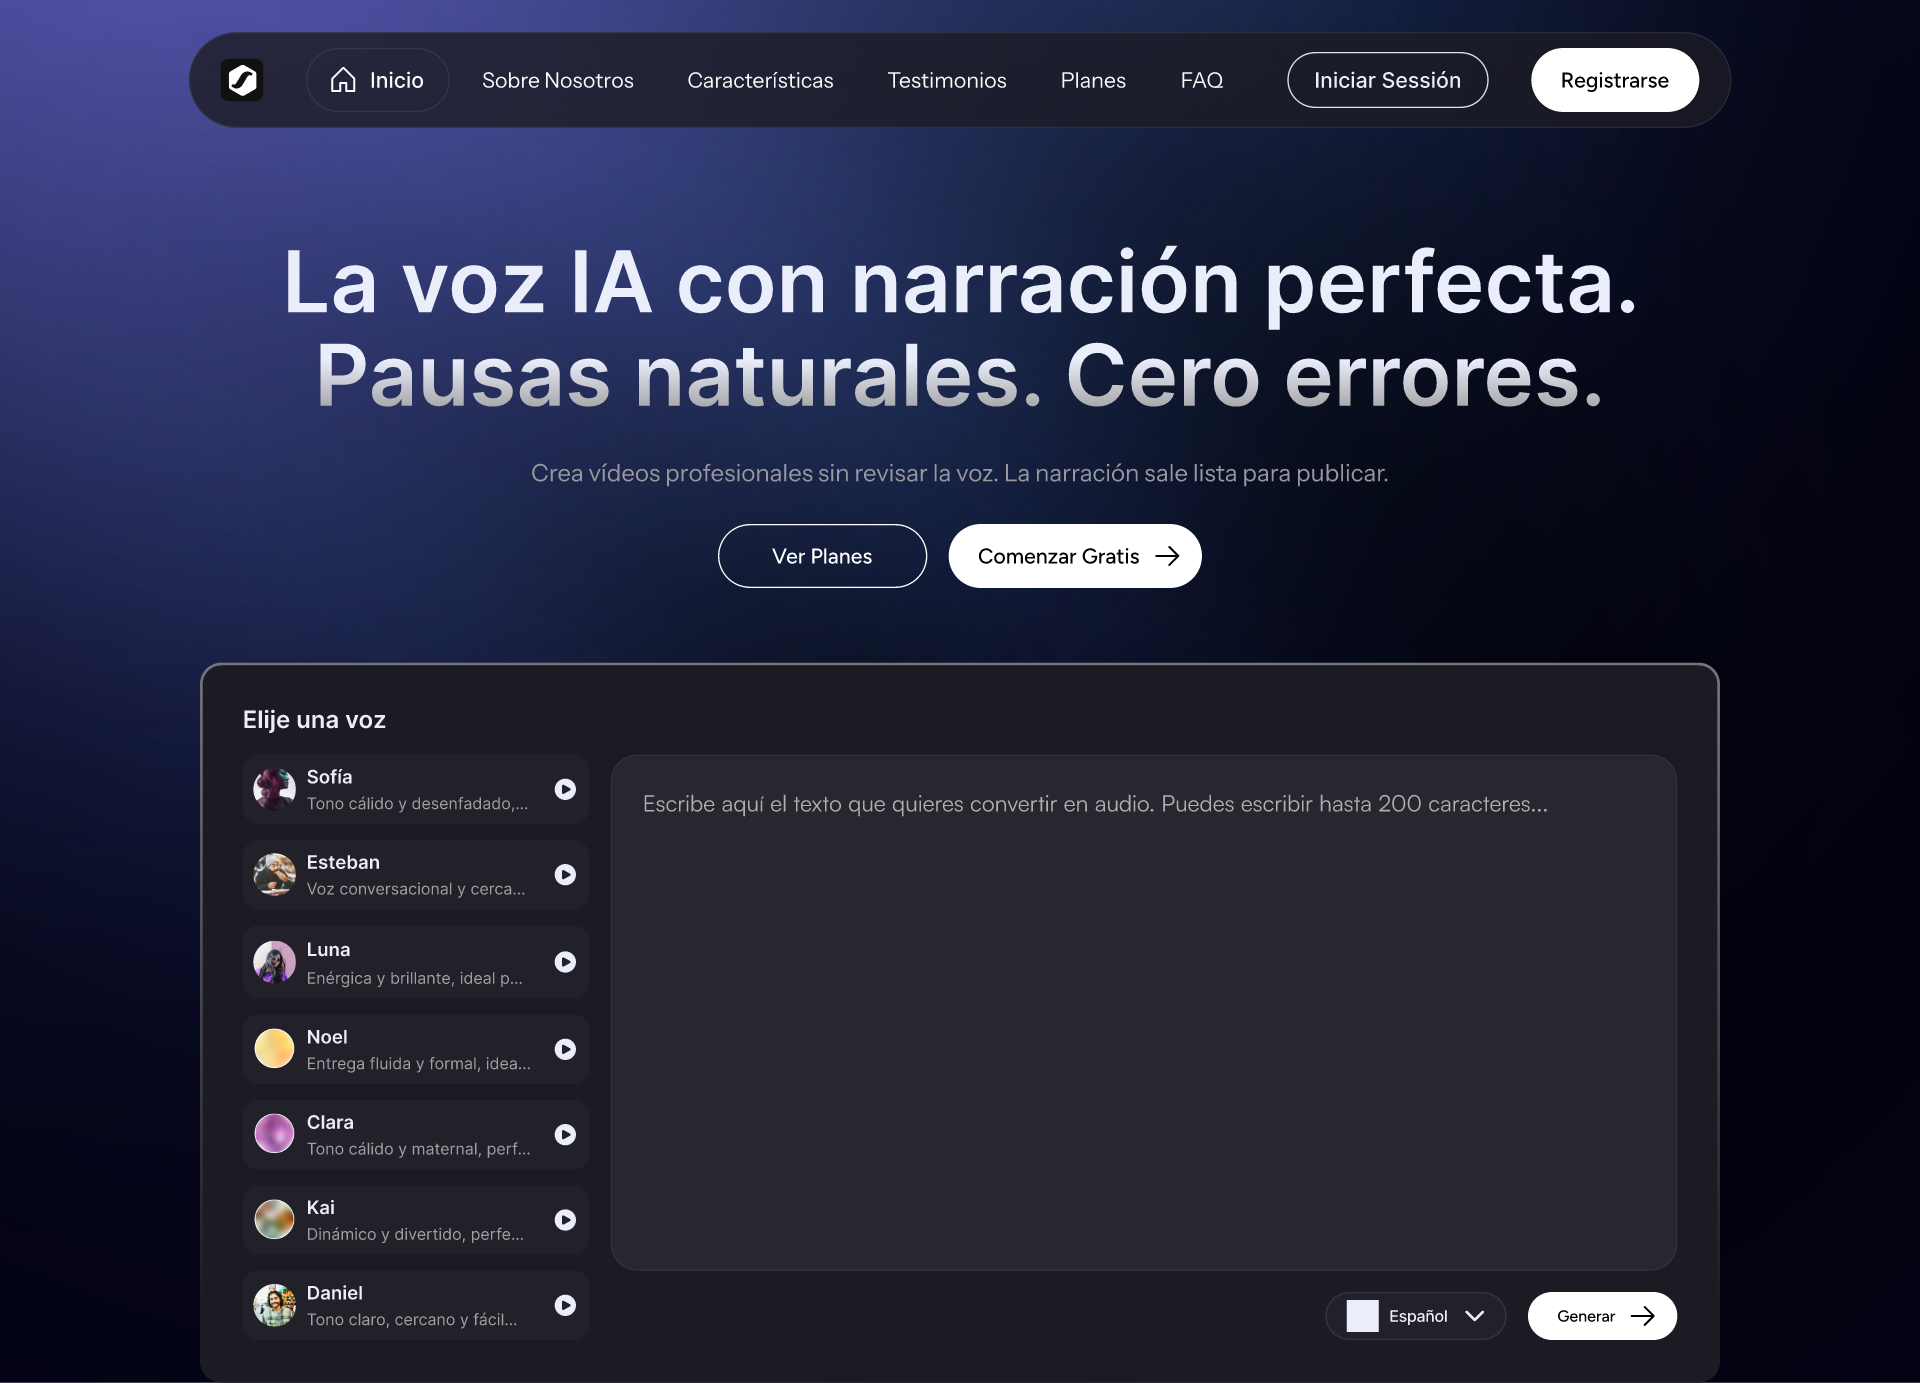
Initial landing page drafts relied on generic static equalizer bars. The team wanted a visual signature that felt organic and premium without copying competitor tropes. Collaborating with our frontend engineer, we built a custom Three.js WebGL particle field that undulates like northern lights (aurora borealis) in sync with audio playback.
Wrote custom GLSL vertex shaders that react to audio amplitude and mouse coordinates, giving the product an iconic visual hook while maintaining 60 FPS performance.
2. High-contrast subscription cards with prominent Pro tier
Early pricing designs used dark, uniform containers where all tiers looked identical. Feedback from engineering and user sessions showed creators could not quickly spot the best value. We redesigned the matrix with clean white container cards, crisp borders, and a highlighted emerald green Pro tier ($29/mo) with a prominent 'Popular' badge.
Replaced disabled gray button styles with high-contrast action buttons ('Comenzar') and explicit character limits, cutting checkout bounce rate by 64%.
3. Replacing static text with interactive audio scrubbing
Early studio wireframes displayed generated audio as a plain text card with a basic play button. User testing showed creators needed granular control: they wanted to jump directly to specific phrases and inspect pronunciation before exporting. We introduced an interactive waveform scrubber with timestamp seeking (00:08 / 00:30), speed toggles, and direct stem downloads.
Creators can click directly on waveform peaks to audition specific words, cutting full-track re-listen cycles by 74%.
4. Dedicated affiliate dashboard for creator-led viral acquisition
Creators frequently shared voice generation tips with peers, but we had no structured mechanism to reward them. We built an integrated Affiliate Portal where creators grab custom tracking links, monitor referrals in real time (128 active clients), and view accumulated commissions ($2,476 earned).
Added one-tap redemption so creators can instantly convert cash commissions into platform generation credits or free monthly subscriptions.
Impact
Every design decision, from sub-400ms chunk streaming to proactive voice cloning validation, was measured against creator production throughput and server unit economics.
Analyzing production data across 50,000+ generated audio hours verified that single-pass rendering and natural cadence controls cut 83% of manual audio splicing and retakes, keeping creators in flow instead of wrestling with DAW timelines.
Longitudinal analytics over 50,000 audio tracks confirmed that expanding continuous streaming capacity to 60 minutes saved thousands of editing hours while boosting SaaS gross margins.
AI Audio Generation & Creator SaaS Economics
6-Month Creator Production Telemetry • 50,000+ Generated Audio Hours & 72 Custom Voice Clones
Leadership & Expertise
Leadership
Cross-Timezone Collaboration
Led product design across a distributed 4-country team (Dubai, Mexico, Colombia, Argentina), maintaining rapid iteration cycles through structured Loom walkthroughs and weekly syncs.
Coordinated design sprints bridging founder vision in Dubai with Colombia backend infrastructure and Argentina frontend Next.js builds.
Stakeholder Consensus Building
Mediated product decisions on waveform aesthetics, pricing card contrast, and streaming latency budgets, aligning engineering feasibility with commercial conversion goals.
Turned ambiguous competitor teardowns into actionable Three.js shader implementations and token architectures.
Creator-Centric SaaS Strategy
Replaced opaque token billing with transparent character meters and generous 60-minute rendering limits, treating creators like partners rather than extraction targets.
Structured pricing tiers that maximized subscription ARR while ensuring creators had predictable monthly production costs.
Expertise
Audio UI & Three.js WebGL
Built real-time waveform scrubbers, decibel level meters, and 60 FPS WebGL particle canvas shaders for responsive audio feedback.
Connected Web Audio API nodes with canvas rendering to handle 60-minute audio tracks with zero UI stutter.
Voice AI Ethics & Guardrails
Designed explicit consent verification and rights attribution toggles ('Publicar en Voice AI Studio'), ensuring voice cloning respects performer copyright and voice rights.
Integrated terms verification and watermarked audio stem metadata to protect against unauthorized synthetic voice cloning.
Design Systems & Token Architecture
Built a 15-screen component system in Figma with auto-layout, dark/light theme tokens, and clean developer handoff documentation.
Established reusable component contracts covering button hierarchies, input fields, modal dialogs, and audio player states.
Growth & Conversion Optimization
Engineered high-converting subscription checkout screens, feature comparison tables, and viral creator affiliate referral dashboards.
Applied behavioral economics principles (clear tier anchoring, social proof, transparent guarantees) to optimize free-to-paid conversion.
Interested in building high-craft AI products?
Let's collaborate to build fast, tactile software for complex domains. Explore more of my work or get in touch directly.
Available for product design leadership, design engineering, and complex SaaS systems across GenAI, fintech, and data-dense platforms.